AI Model Conversion and Edge Deployment
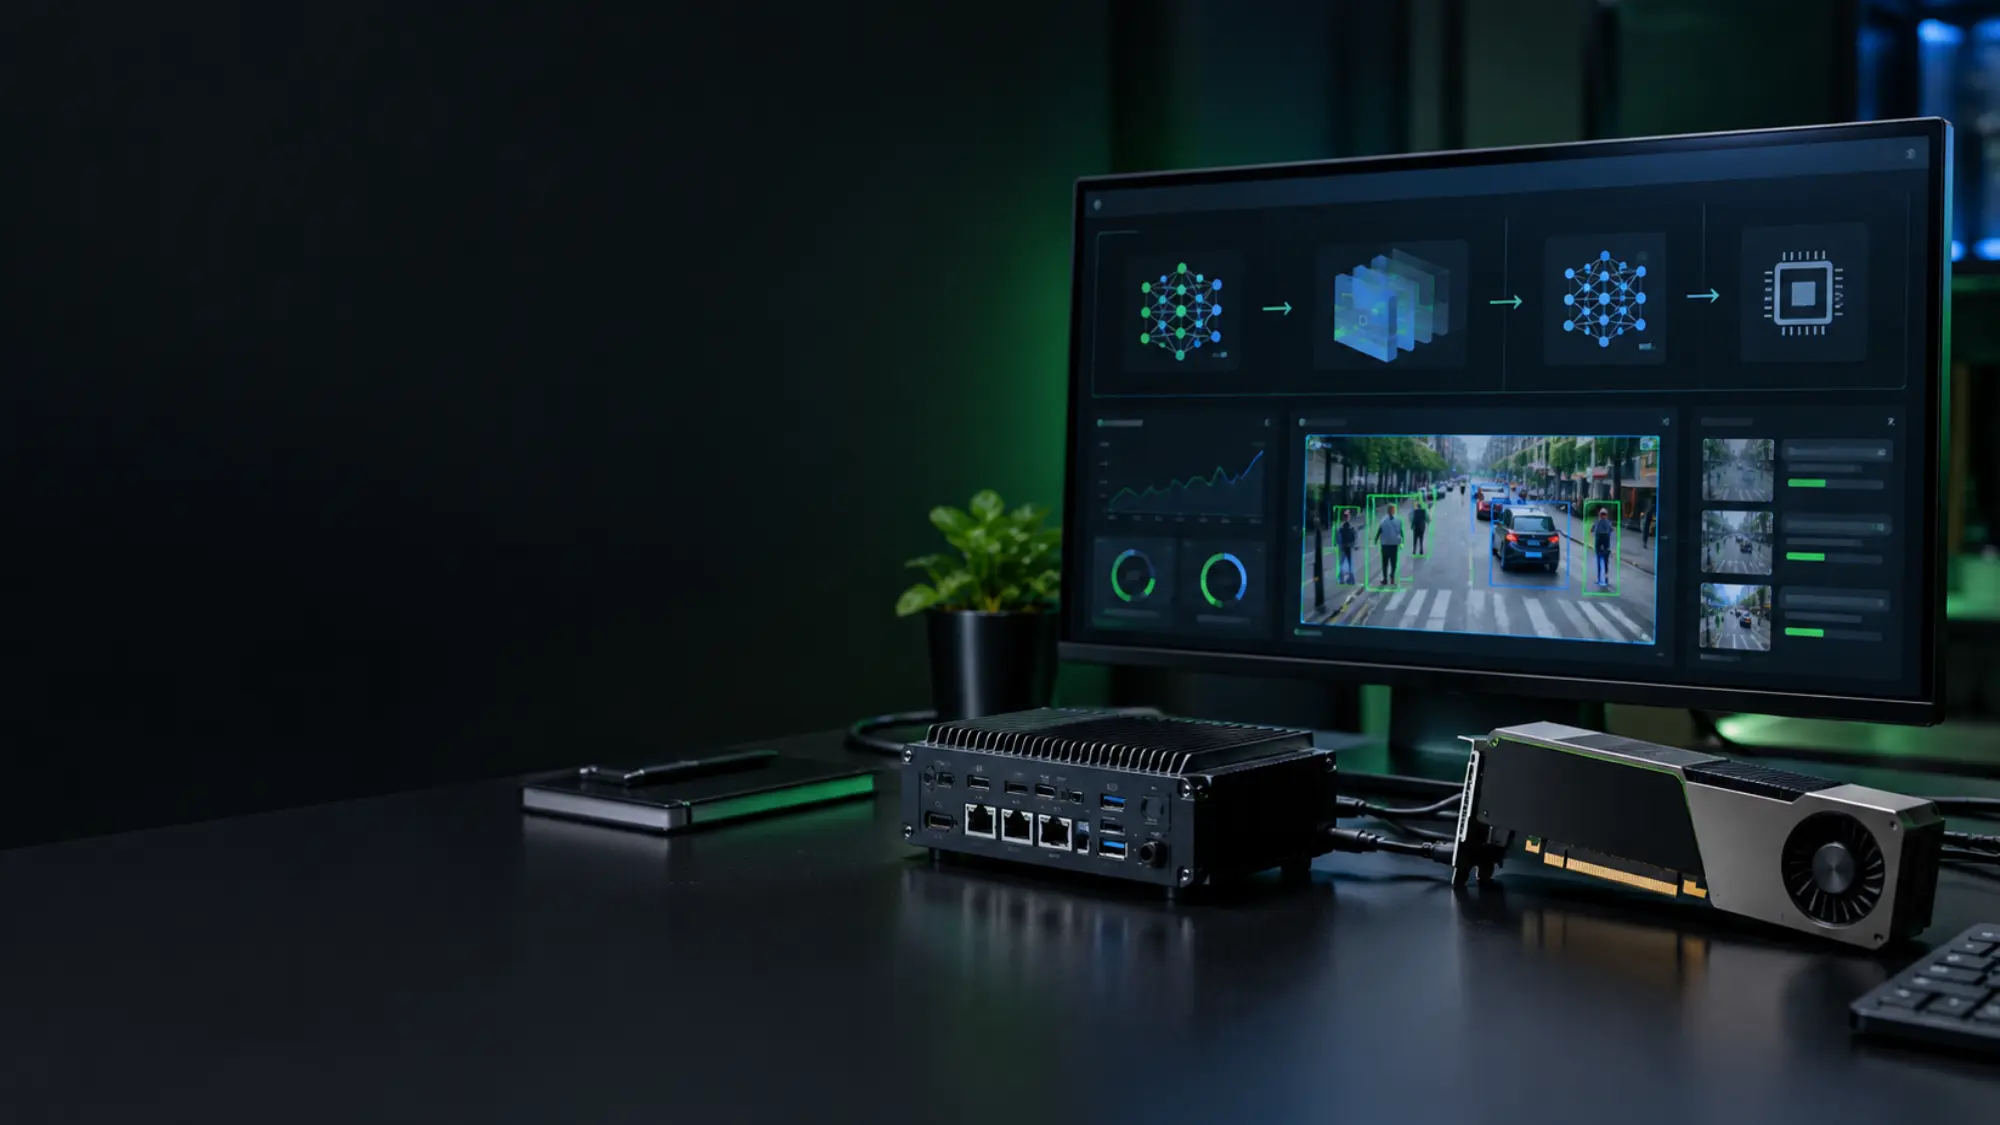
The Challenge
Training a computer vision model is only one part of building a production AI application.
A model that performs successfully in a development environment may still require additional engineering before it can run efficiently on the target hardware. Differences in model operators, inference runtimes, supported precision, memory availability, and video-processing pipelines can create deployment challenges.
The objective is to establish a practical path from a trained AI model to a deployable computer vision inference pipeline.
Deployment Workflow
Rootblock Labs approaches model deployment as an engineering workflow rather than a single model-conversion step.
1. Model Assessment
The first step is to evaluate the trained model, its architecture, operators, input requirements, and target deployment environment.
This helps identify potential compatibility issues before conversion or optimisation begins.
2. Model Conversion
Where appropriate, models can be prepared for deployment formats and inference runtimes such as ONNX and TensorRT.
Conversion requirements depend on the model architecture, operators, target hardware, and supported runtime capabilities.
3. Inference Optimisation
The inference pipeline can then be evaluated for factors such as:
- Inference latency
- Throughput
- Precision
- Memory usage
- Hardware utilisation
- Accelerator-supported execution
The optimisation strategy depends on the application’s performance requirements and target hardware.
4. Video Pipeline Integration
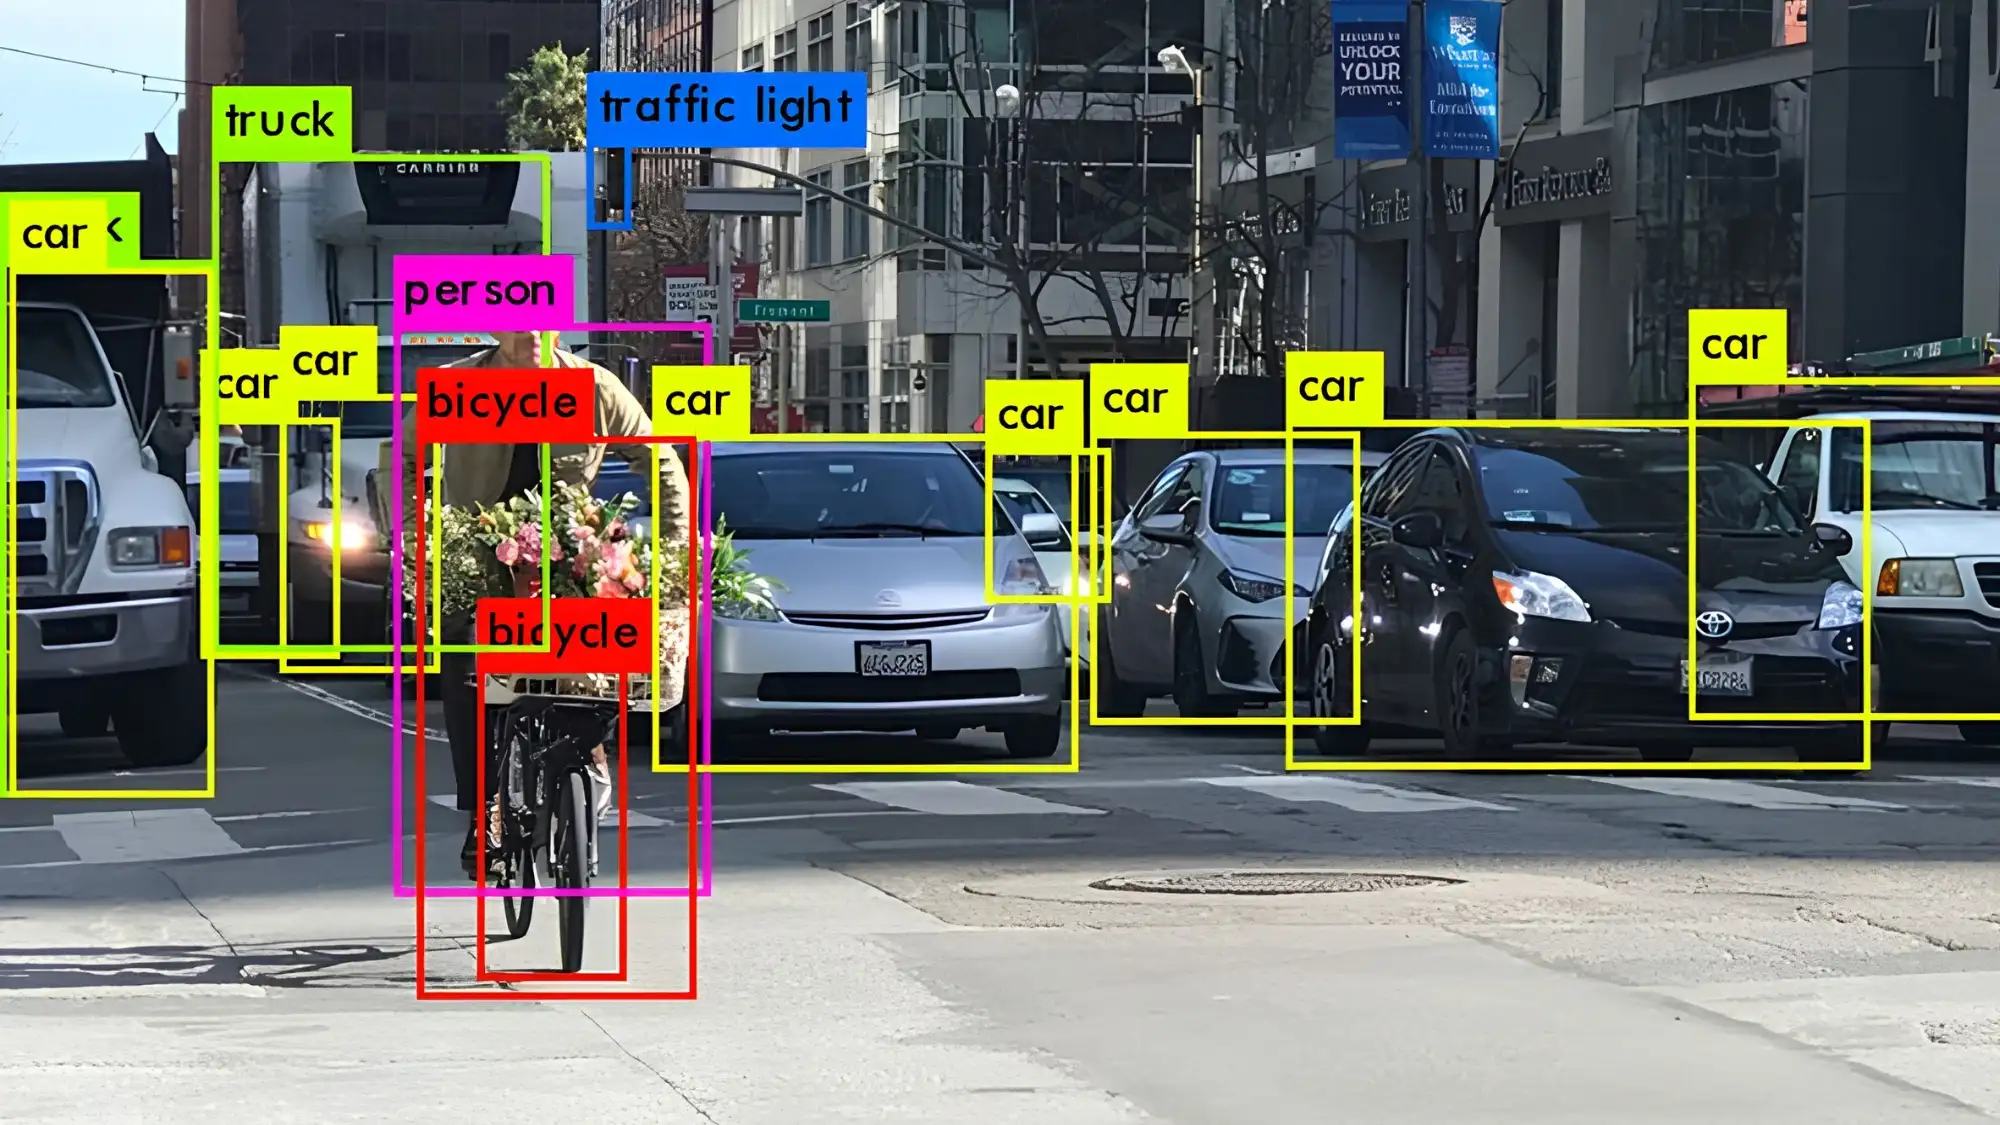
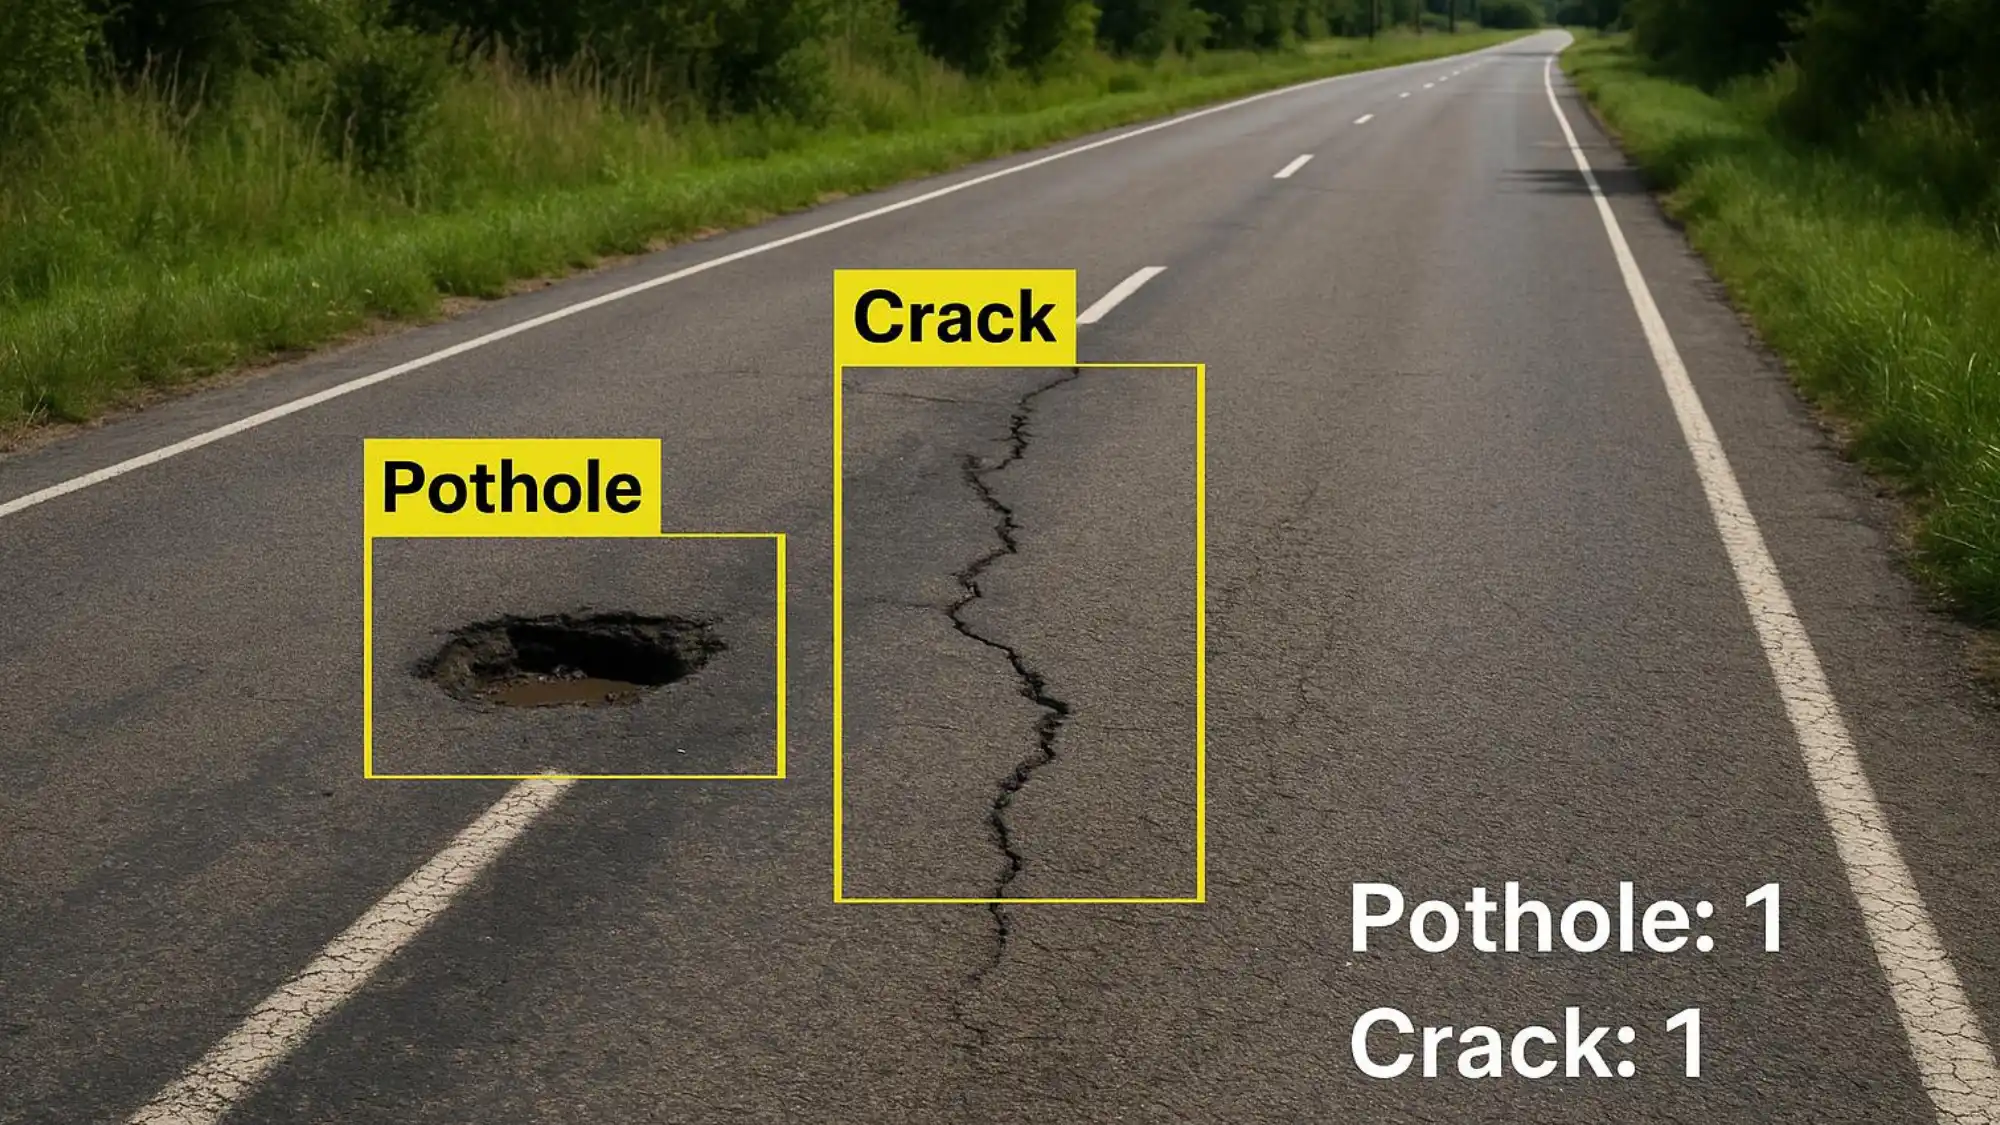
For real-time computer vision applications, model inference must operate as part of a larger video pipeline.
Rootblock Labs works with technologies such as:
- RTSP
- GStreamer
- FFmpeg
- OpenCV
- NVIDIA DeepStream
These technologies can be used to connect video ingestion, preprocessing, inference, and downstream processing.
5. Performance Evaluation
Deployment readiness requires measurable evaluation.
Depending on the project, relevant metrics may include:
- FPS
- End-to-end latency
- Inference latency
- Memory consumption
- GPU/accelerator utilisation
- Stream capacity
- Resource utilisation
Measurements should be compared against predefined application requirements.
Deployment Outcome
The specific project results depend on the model, target hardware, runtime, and application architecture.
For this capability showcase, Rootblock Labs does not claim a specific percentage improvement in latency, model size, or throughput without documented before-and-after measurements.
Why This Matters
A successful AI deployment requires more than model accuracy. The model must also operate within the latency, throughput, memory, hardware, and integration constraints of the target application.
Rootblock Labs helps engineering teams identify these constraints early and establish a measurable path from trained model to deployable computer vision system.
Technologies
Rootblock Labs Capability
Have a trained AI model that needs to run on edge hardware? Rootblock Labs can help evaluate model compatibility, select an appropriate deployment path, optimise inference, and integrate the model into a real-time computer vision pipeline.