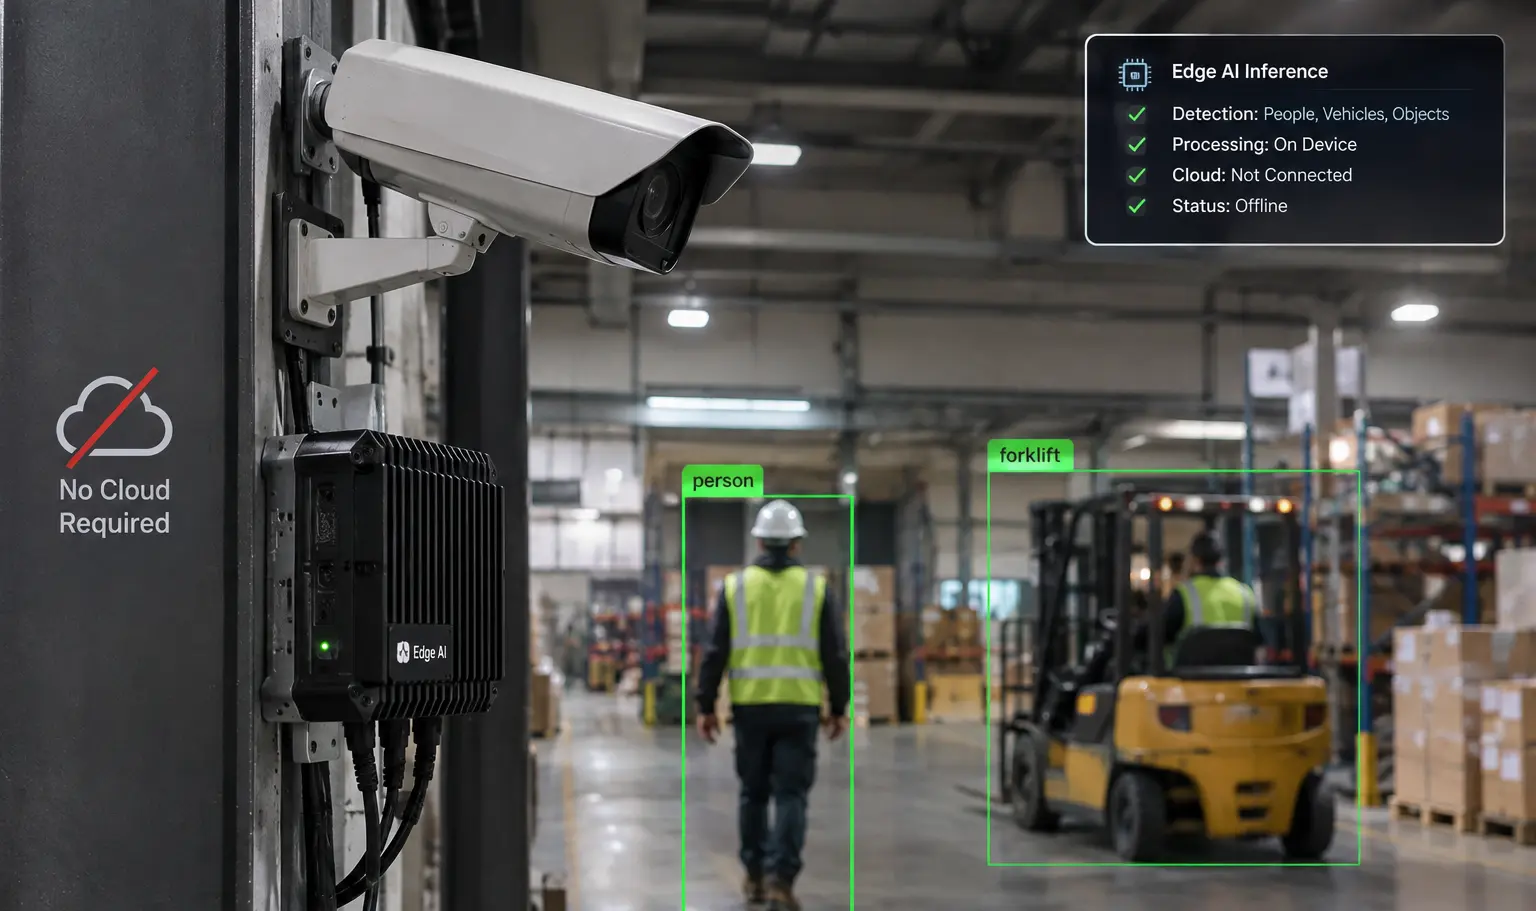
Custom Edge AI Development
Inference Applications designed around your Cameras, Sensors, Latency Limits, and the Decisions that can’t wait on a Network Round Trip.
Discuss a Project
RootBlock Labs builds, converts, and deploys AI Models that run directly on industrial Edge Hardware. We handle Development, Optimization, Hardware Integration, and on-device Deployment for Computer Vision Workloads.
Most Industrial Sites weren’t built around a Data Center’s Network. Mines, Substations, and Construction Sites can have patchy Connectivity; running Inference on Hardware at the Site is often the only way to get a useful Decision from a Camera in time.
Edge AI keeps working when the Connection drops, and most raw Video never has to leave the Building.
| Consideration | Edge AI | Cloud AI |
|---|---|---|
| Where Inference Runs | On Hardware at your Site | In a remote Data Center |
| Response Time | Local, without a Network Round Trip | Depends on the Network |
| Without Internet | Keeps working | Stops working |
| Video and Sensor Data | Mostly stays on Site | Sent off Site |
| Best Fit | Real-time Safety and Security | Large-scale, non-time-critical Analysis |
Edge AI projects fail between the trained Model and the Device on Site. We cover that gap: the Model, Accelerator, Camera Streams, and Deployment.
Inference Applications designed around your Cameras, Sensors, Latency Limits, and the Decisions that can’t wait on a Network Round Trip.
Discuss a Project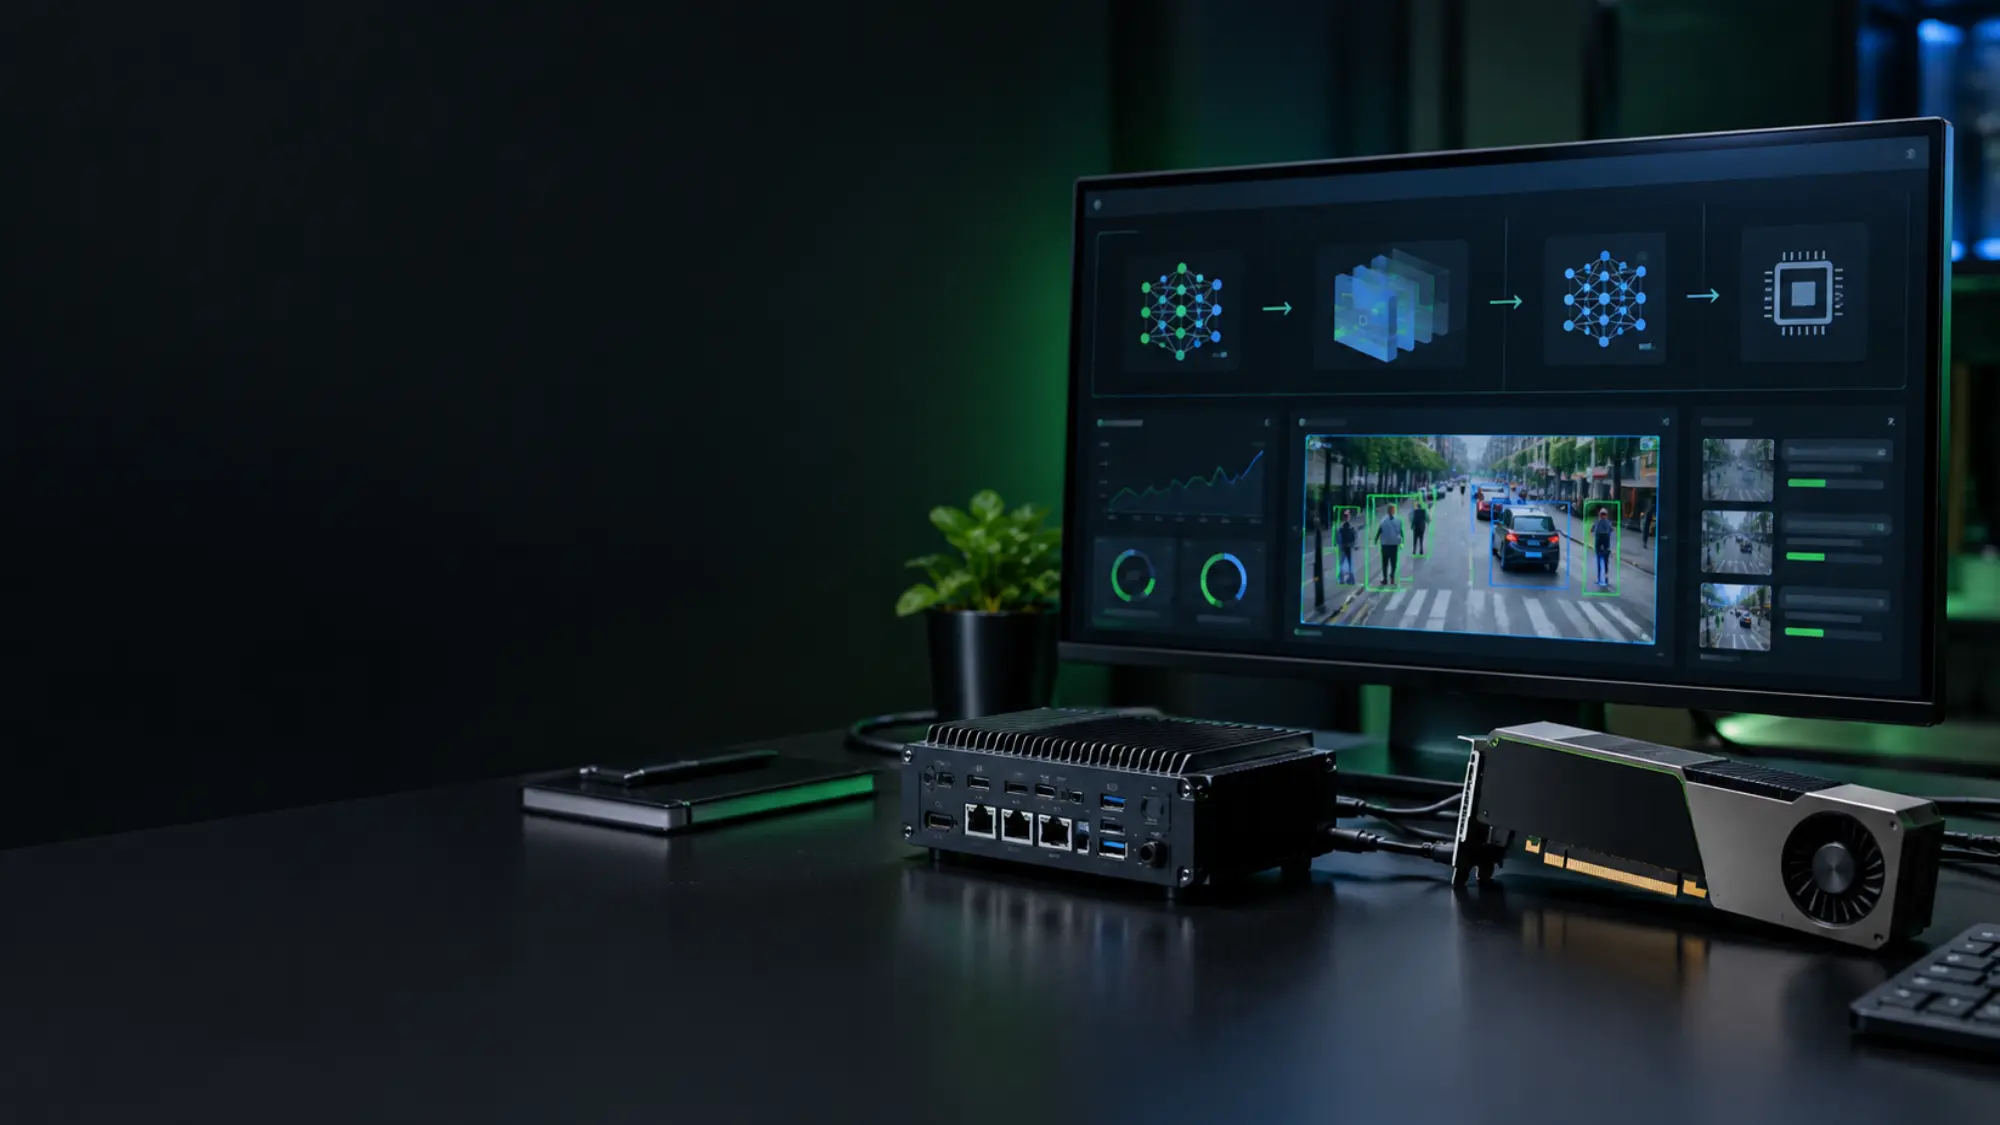
We convert and quantize trained Models for the target Accelerator, then check Accuracy against the original.
Read the Conversion Case Study
We match Models to Accelerators within your Power, Thermal, and Enclosure Limits, and connect them to the CCTV and Camera Infrastructure you already have.
Plan an Integration
Engineering for Workloads that spread many Streams across several Accelerators.
Read the Engineering Case Study
We install, configure, and validate Models on Site Hardware, with Edge MLOps to monitor and update them once they’re live.
Discuss Deployment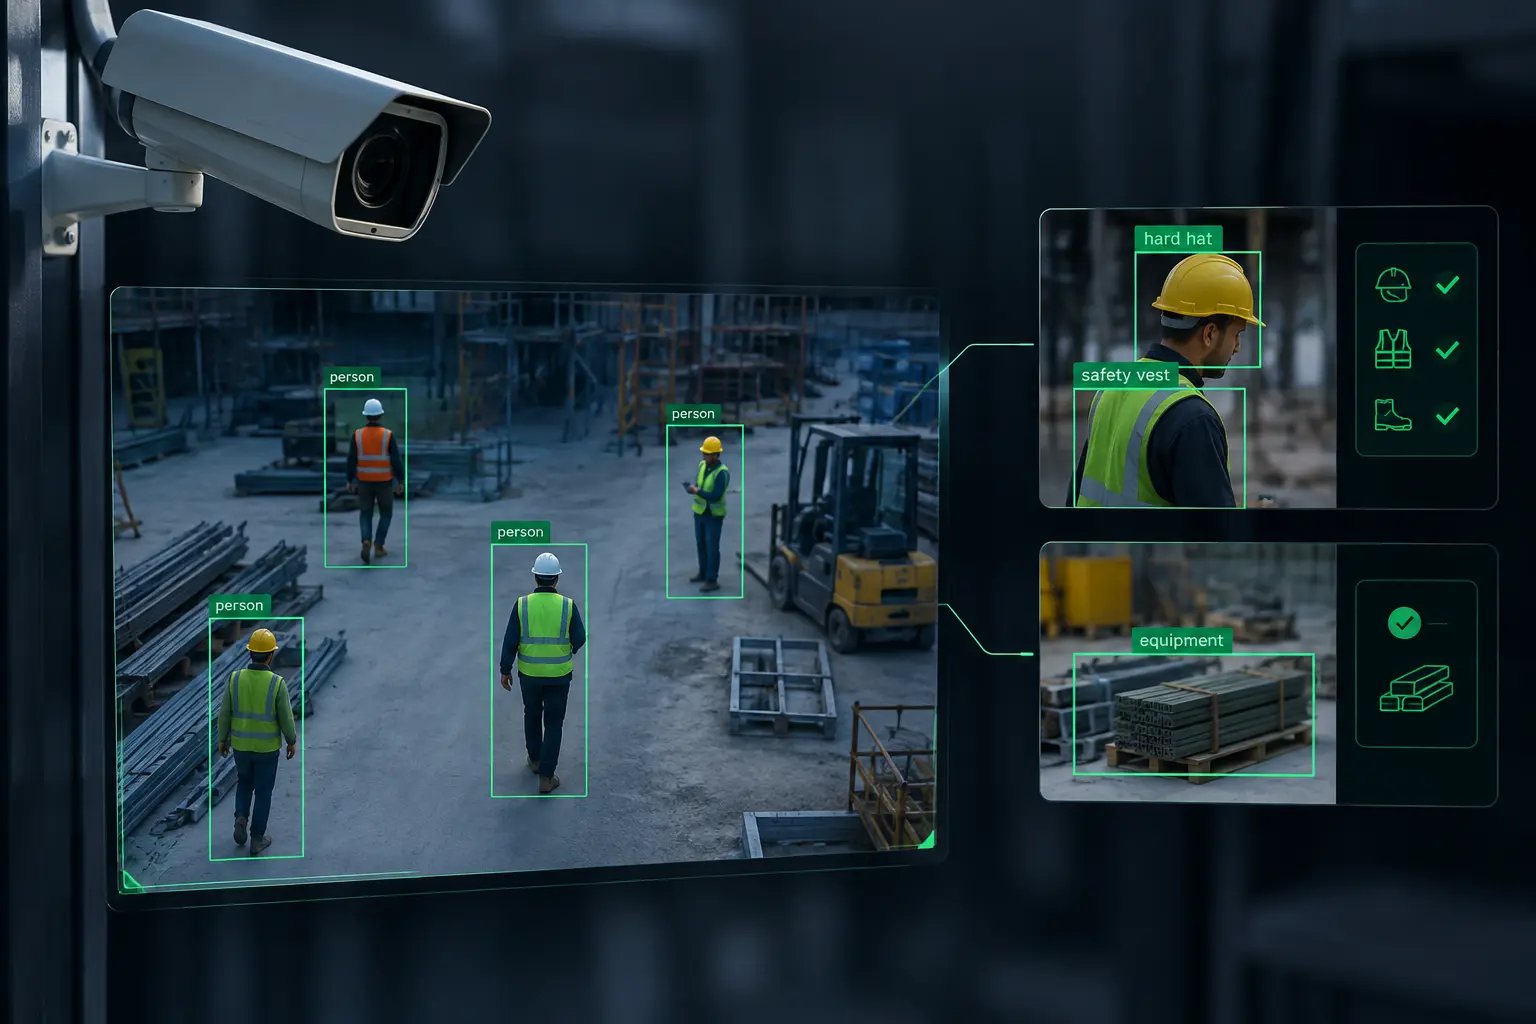
Object Detection and Video Analytics that run locally, so raw Video rarely has to leave the Site.
See Computer VisionA Model that works in Training won’t necessarily run well on an Accelerator. We take it through five Stages and measure the Result on the real Device.
We review the Architecture, Input Size, and Accuracy Target, and flag Operations the chosen Accelerator may not support.
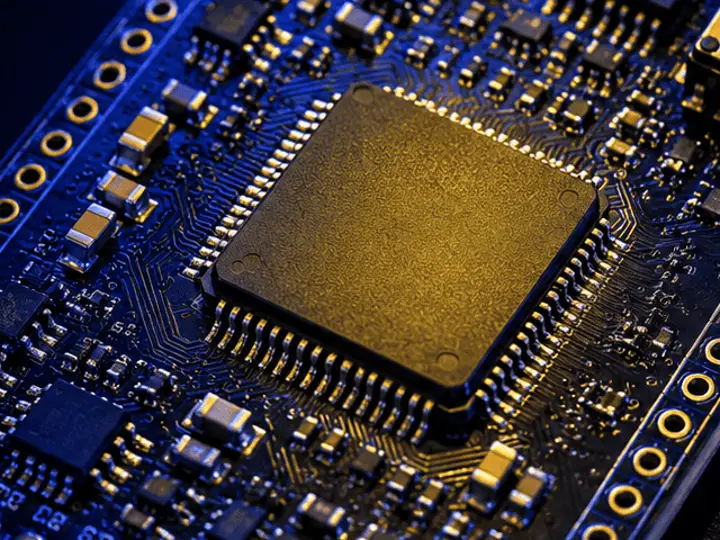
Illustrative Embedded Board, not a RootBlock Labs Deployment. Hover or focus the Markers.
The Accelerator is one part of the System. We fit the Model to the whole Node, so it keeps running at the Site’s real Power, Heat, and Network Conditions.
Inference, Alerts, and Monitoring sit on Site. Only what you choose—such as Event Summaries or Model Updates—crosses the Network.
Video Decode, Inference, and Alerts run locally, without waiting on a Network Round Trip.
Send Event Summaries, Health Status, and Model Updates through Edge MLOps—not every raw Frame.
Each Edge Node is a Network Endpoint. Our Cybersecurity Team reviews the Hardware and its Connections.
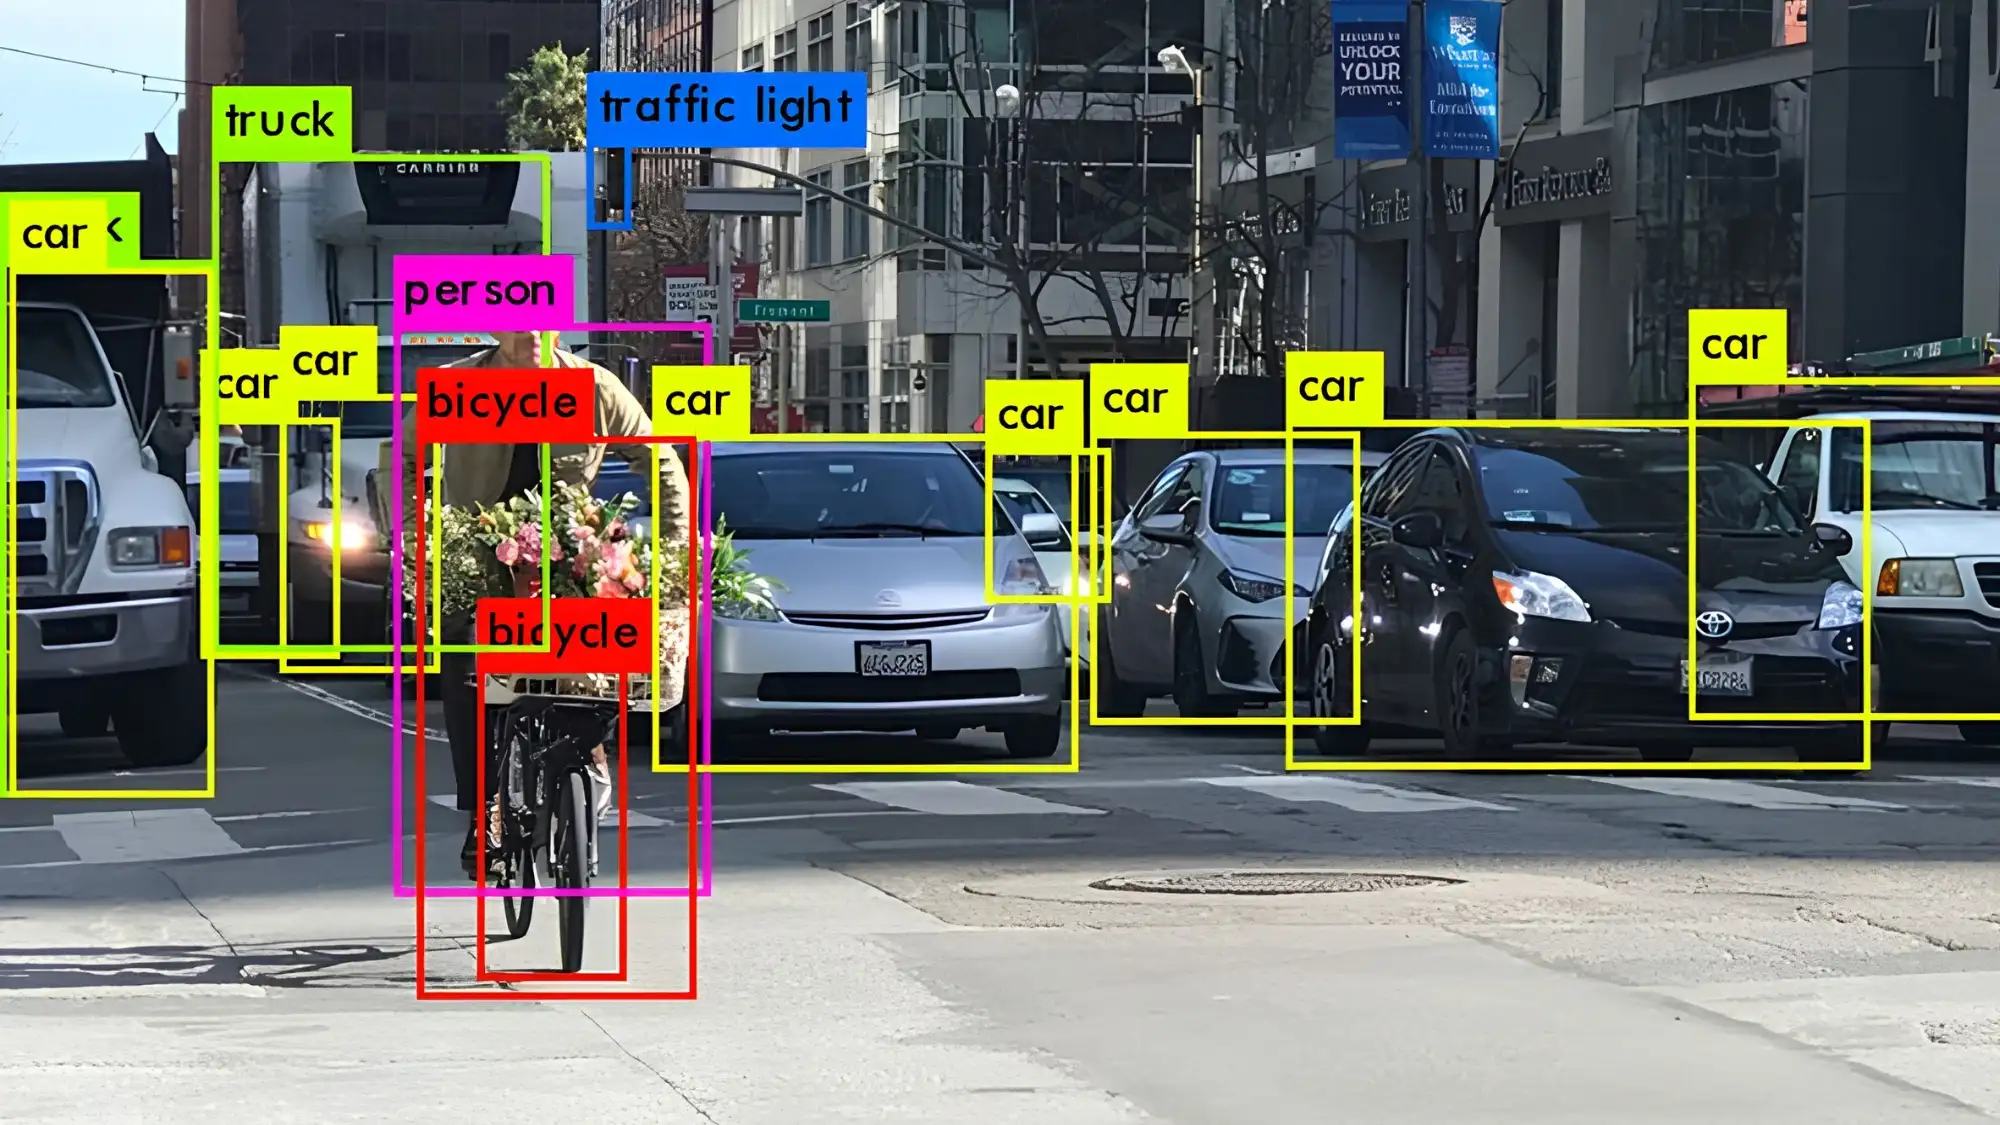
An internal Engineering Benchmark used YOLOv8n on a Blaize X1600 GSP at 416 × 244 Resolution. Throughput depends on the Model, Resolution, Precision, and Pipeline; we measure again on your target Hardware before committing to a Design.
Read the Benchmark Write-upEdge Inference fits Sites with limited Connectivity, safety-critical Decisions, and Cameras already in place.
ManufacturingLine-level Inspection and Equipment Monitoring without routing every Frame to a Data Center.Explore manufacturing 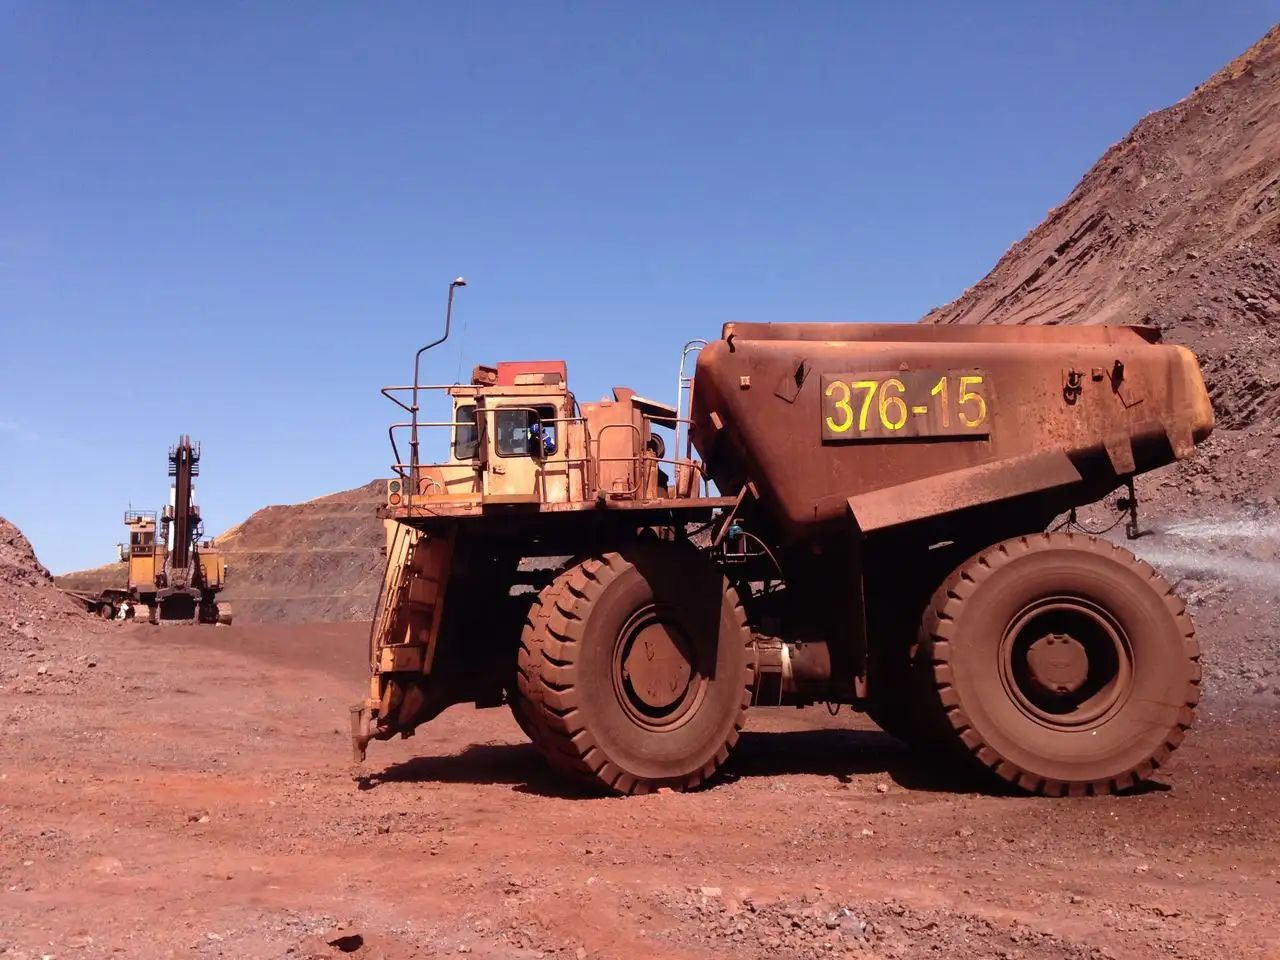 MiningRemote Operations where Connectivity is limited and Decisions are safety-related.Explore mining
 LogisticsVehicle and Pedestrian Conflict Detection across Yards and Docks.Explore logistics
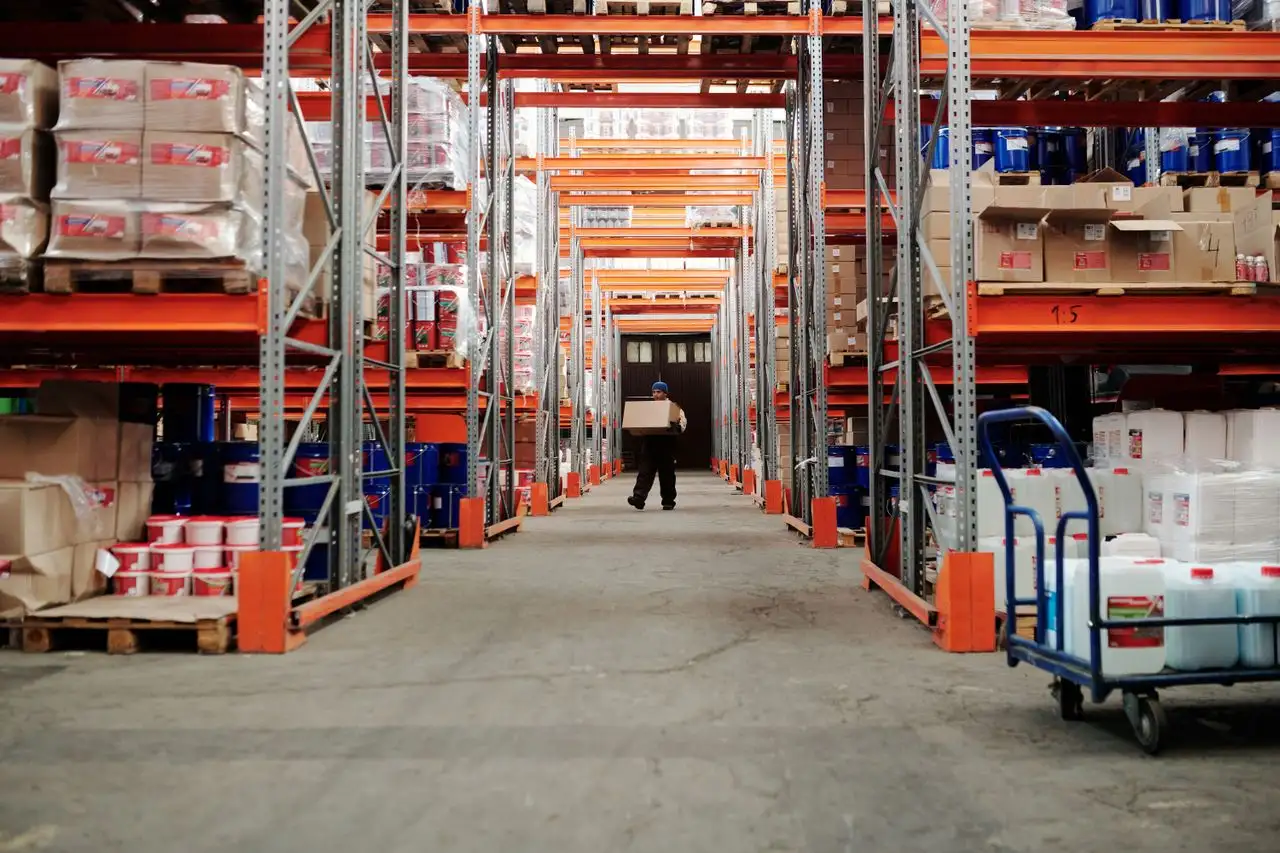 WarehousingZone Monitoring and PPE Compliance on existing Cameras.Explore warehousing EnergyRemote Assets and Substations where Connectivity is the exception.Explore energy
A Proof of Concept on real Hardware comes before a Commitment to Scale.
We define the Detections that matter first, review Cameras, Power, and Network, and set clear Expectations for what Edge Hardware can do.
We prepare the Model for the chosen Accelerator and set the Accuracy and Throughput Targets it has to meet.
We run the Workload on the actual Device and report measured Results, not Estimates.
We install on Site, secure the Nodes, and set up Monitoring and Model Updates.
Technical Write-ups of how we Benchmark, Convert, and Deploy on Edge Hardware.
A measured YOLOv8n Benchmark on a Blaize X1600 GSP at 416 × 244 Resolution.
100+ FPS Engineering BenchmarkRead Case StudyEngineering a Video Analytics Architecture across NVIDIA and Blaize Accelerators.
Read Case StudyAn Engineering Workflow from trained Model to Deployable Inference Pipeline.
Read Case StudyWe take trained Models to a specific Accelerator and verify Accuracy before and after.
We design for Workloads that spread many Streams across several Accelerators.
Most Deployments reuse existing Cameras, adding an Intelligence Layer instead of new Devices on the Pole.
Scoping and Feasibility, Model Conversion and Optimization for the target Accelerator, Hardware Integration, Validation on the Device, and on-site Deployment with Monitoring. We agree the Scope with you before Work begins.
Tell us what you want to Detect, where, and on what Hardware. An Engineer will reply with next Steps. A Feasibility Assessment is scoped before any Commitment.
Fields marked with an asterisk are required.